The Ask LukeW feature on my Web site has been answering people's product design questions using my writings, talks, images, and videos for over three years. During that time, I've seen people ask lots of different kinds of questions. So we rebuilt the system to answer more of them, better. Here's how.
Not all questions are the same. Some are time bound: "What did you write about Web forms in 2010?" Some require specific a format: "Any videos where you talk about onboarding?" Some want a concrete number: "How many talks did you give in Seattle?" Some are just off topic: "Ever dance with a capybara?" Despite this, the way Ask LukeW previously found answers was always the same.
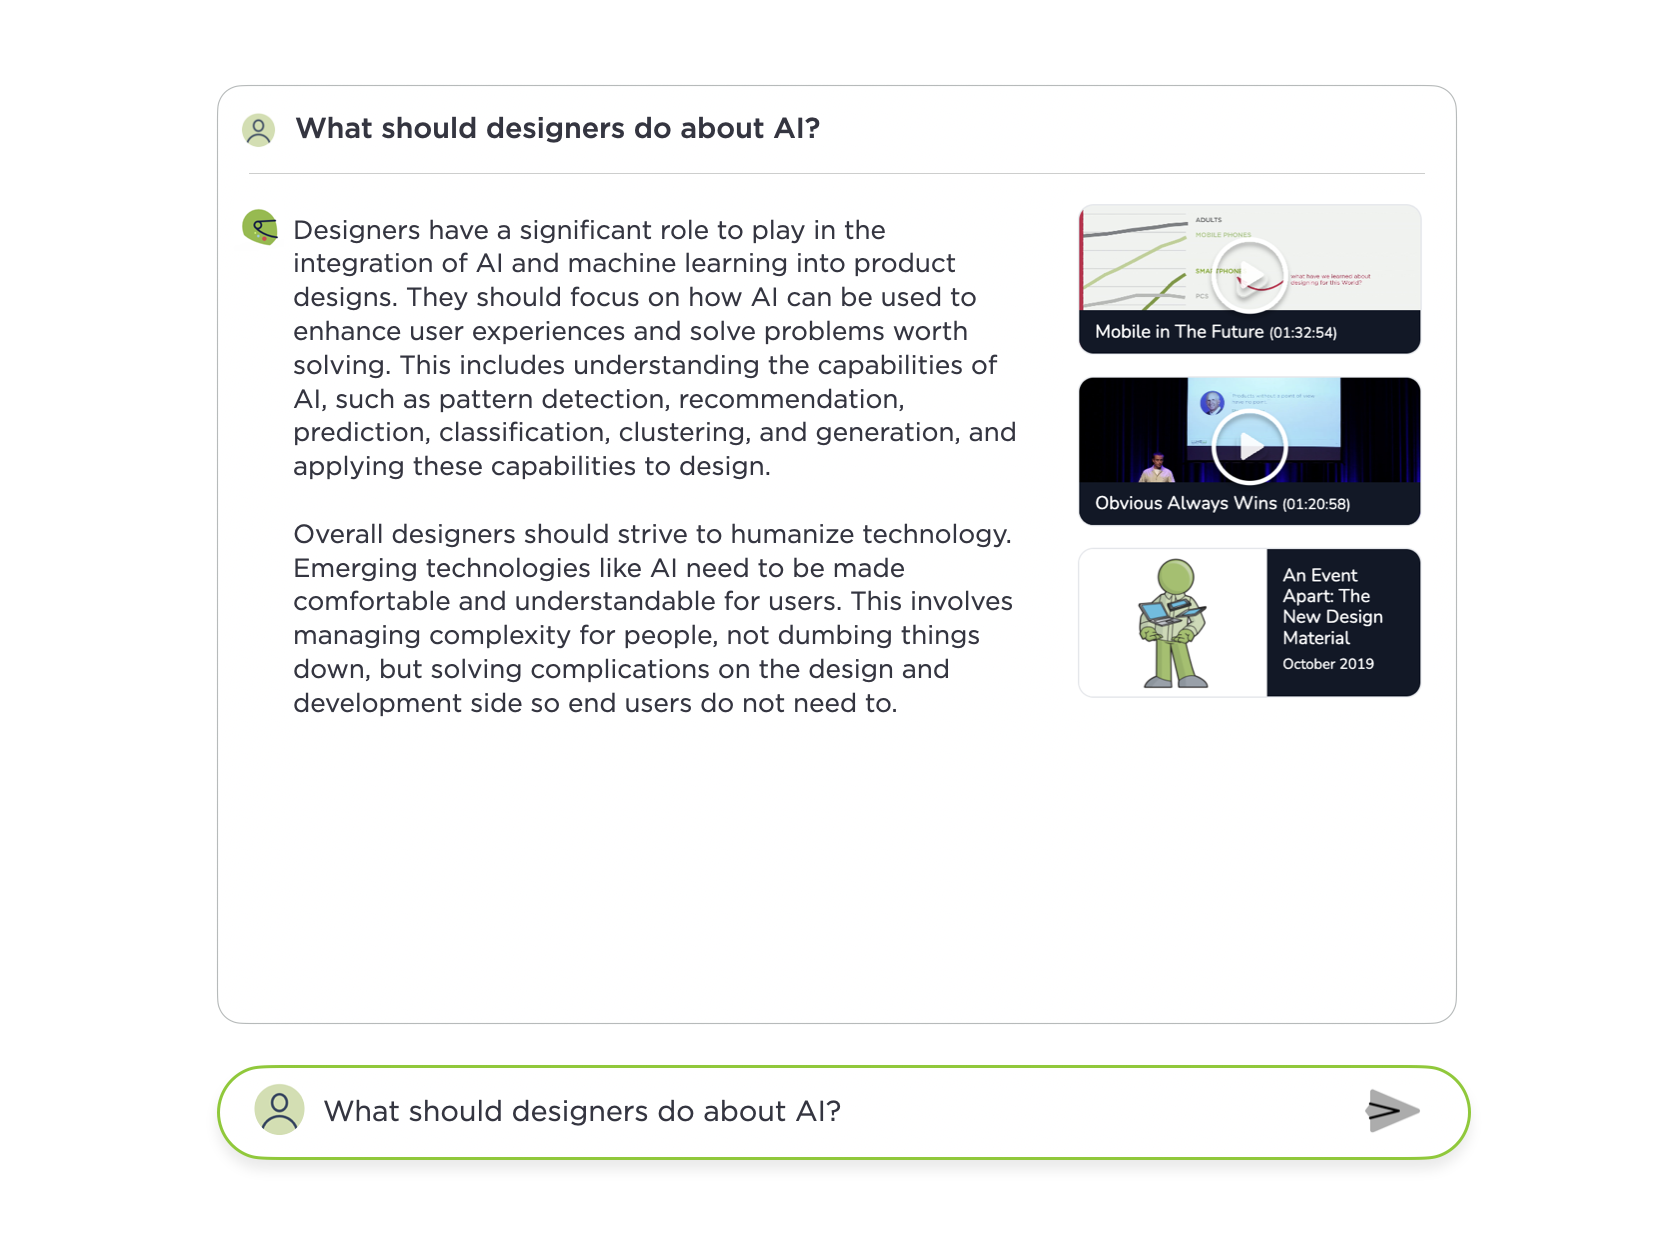
When someone asked a question before, the system ran through four searches at once: semantic and keyword across both titles and contents. Why so many searches at once? A relevant detail can sit deep inside an article whose title looks unrelated, and a strong title match can surface a whole relevant file instead of just passages. The results that come back get merged, deduplicated so we don't repeat the same content multiple times, and re-ranked before being used to answer someone's question.
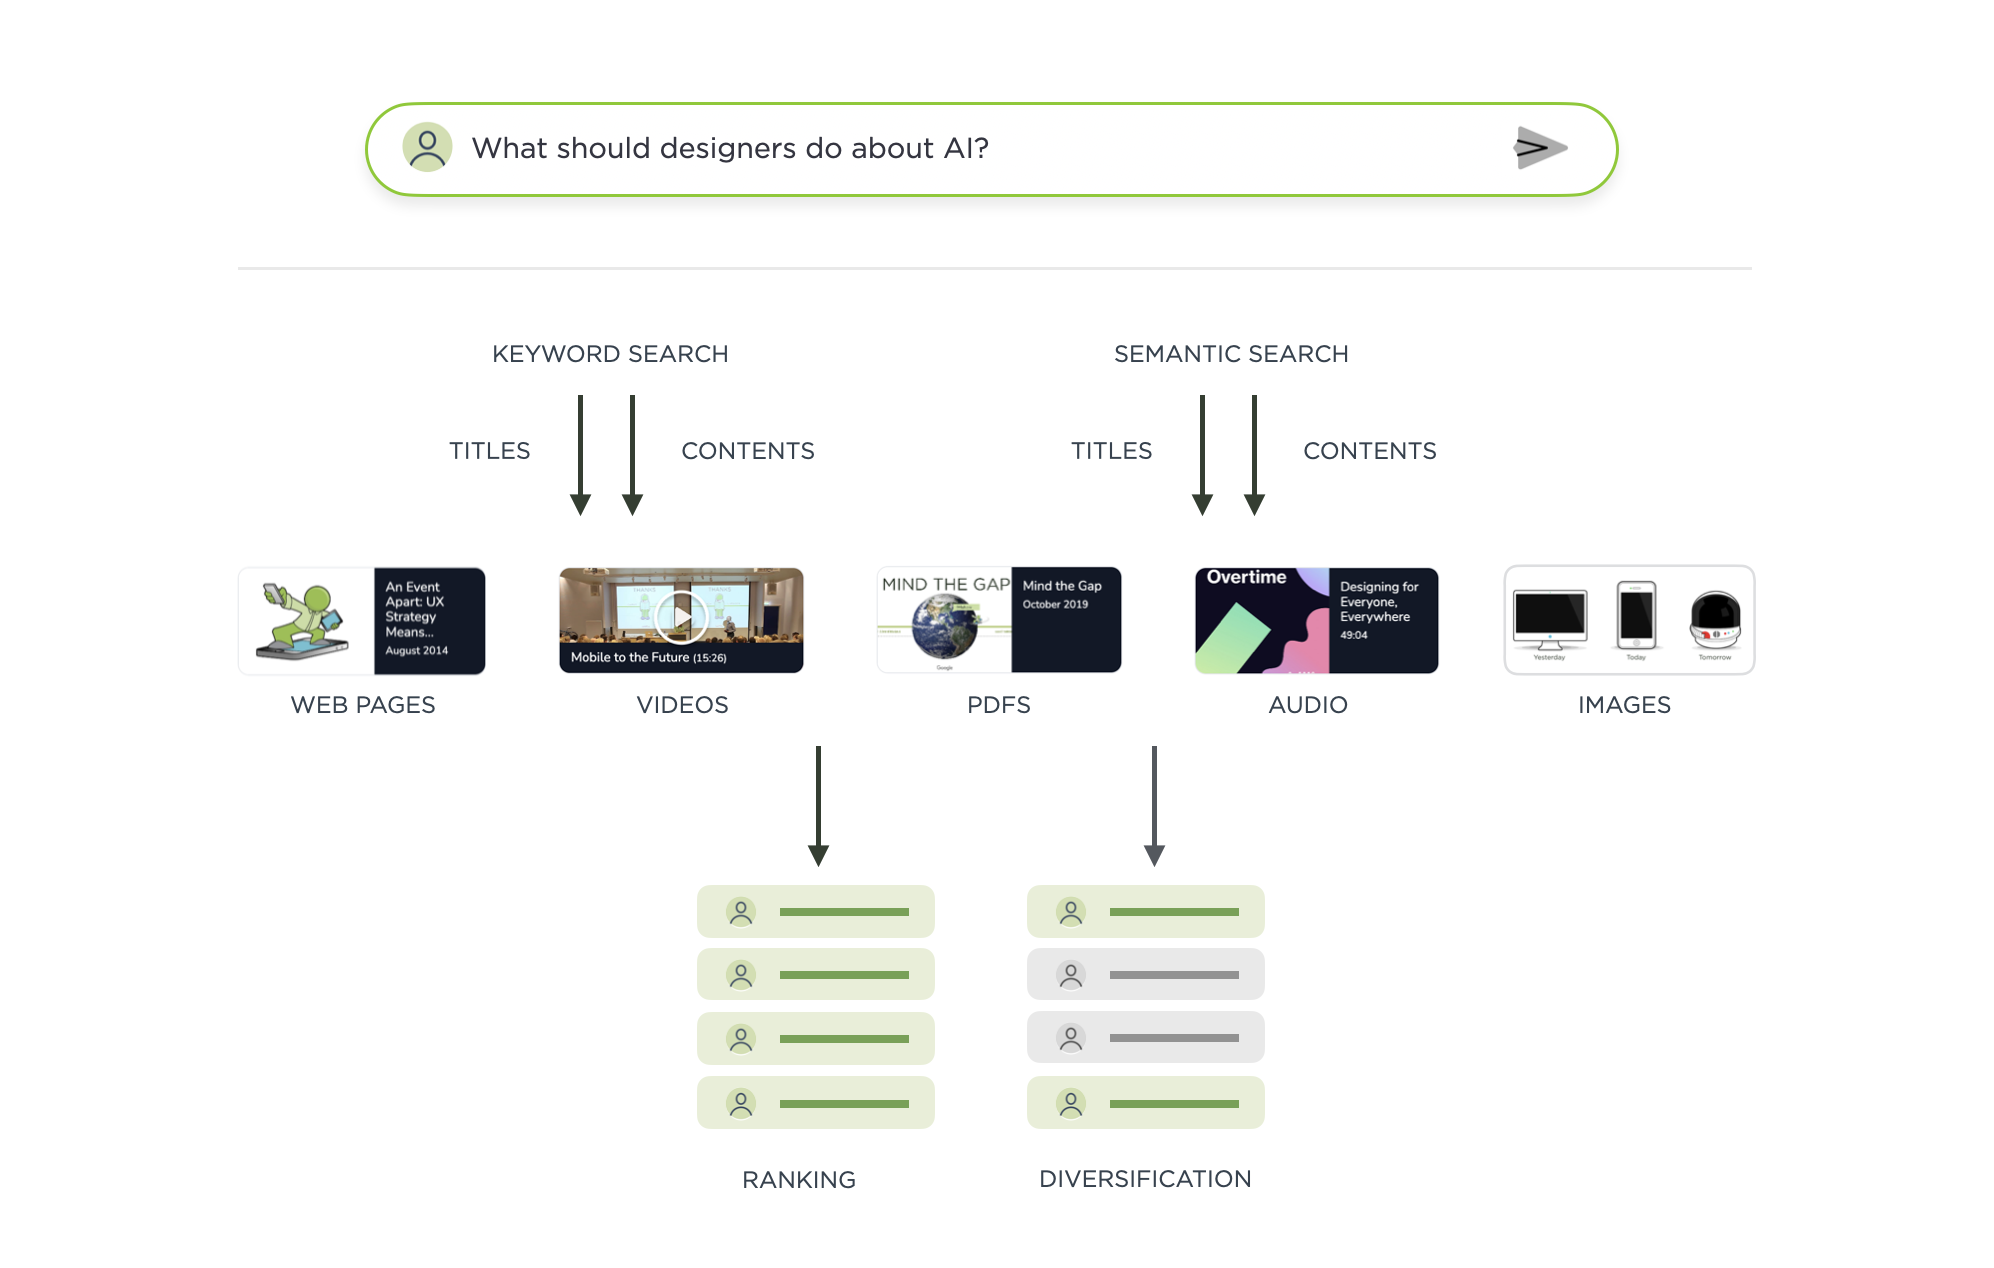
This approach worked well enough to answer the 50,000+ questions people asked to date. But since it was architected three years ago, things have progressed. Very fast and capable AI models can now layer bits of intelligence into places they previously would have been to slow and expensive to use. Context windows for models have massively expanded in size and new models and ways to embed content open up better ways to do retrieval. So... it was time to rebuild.
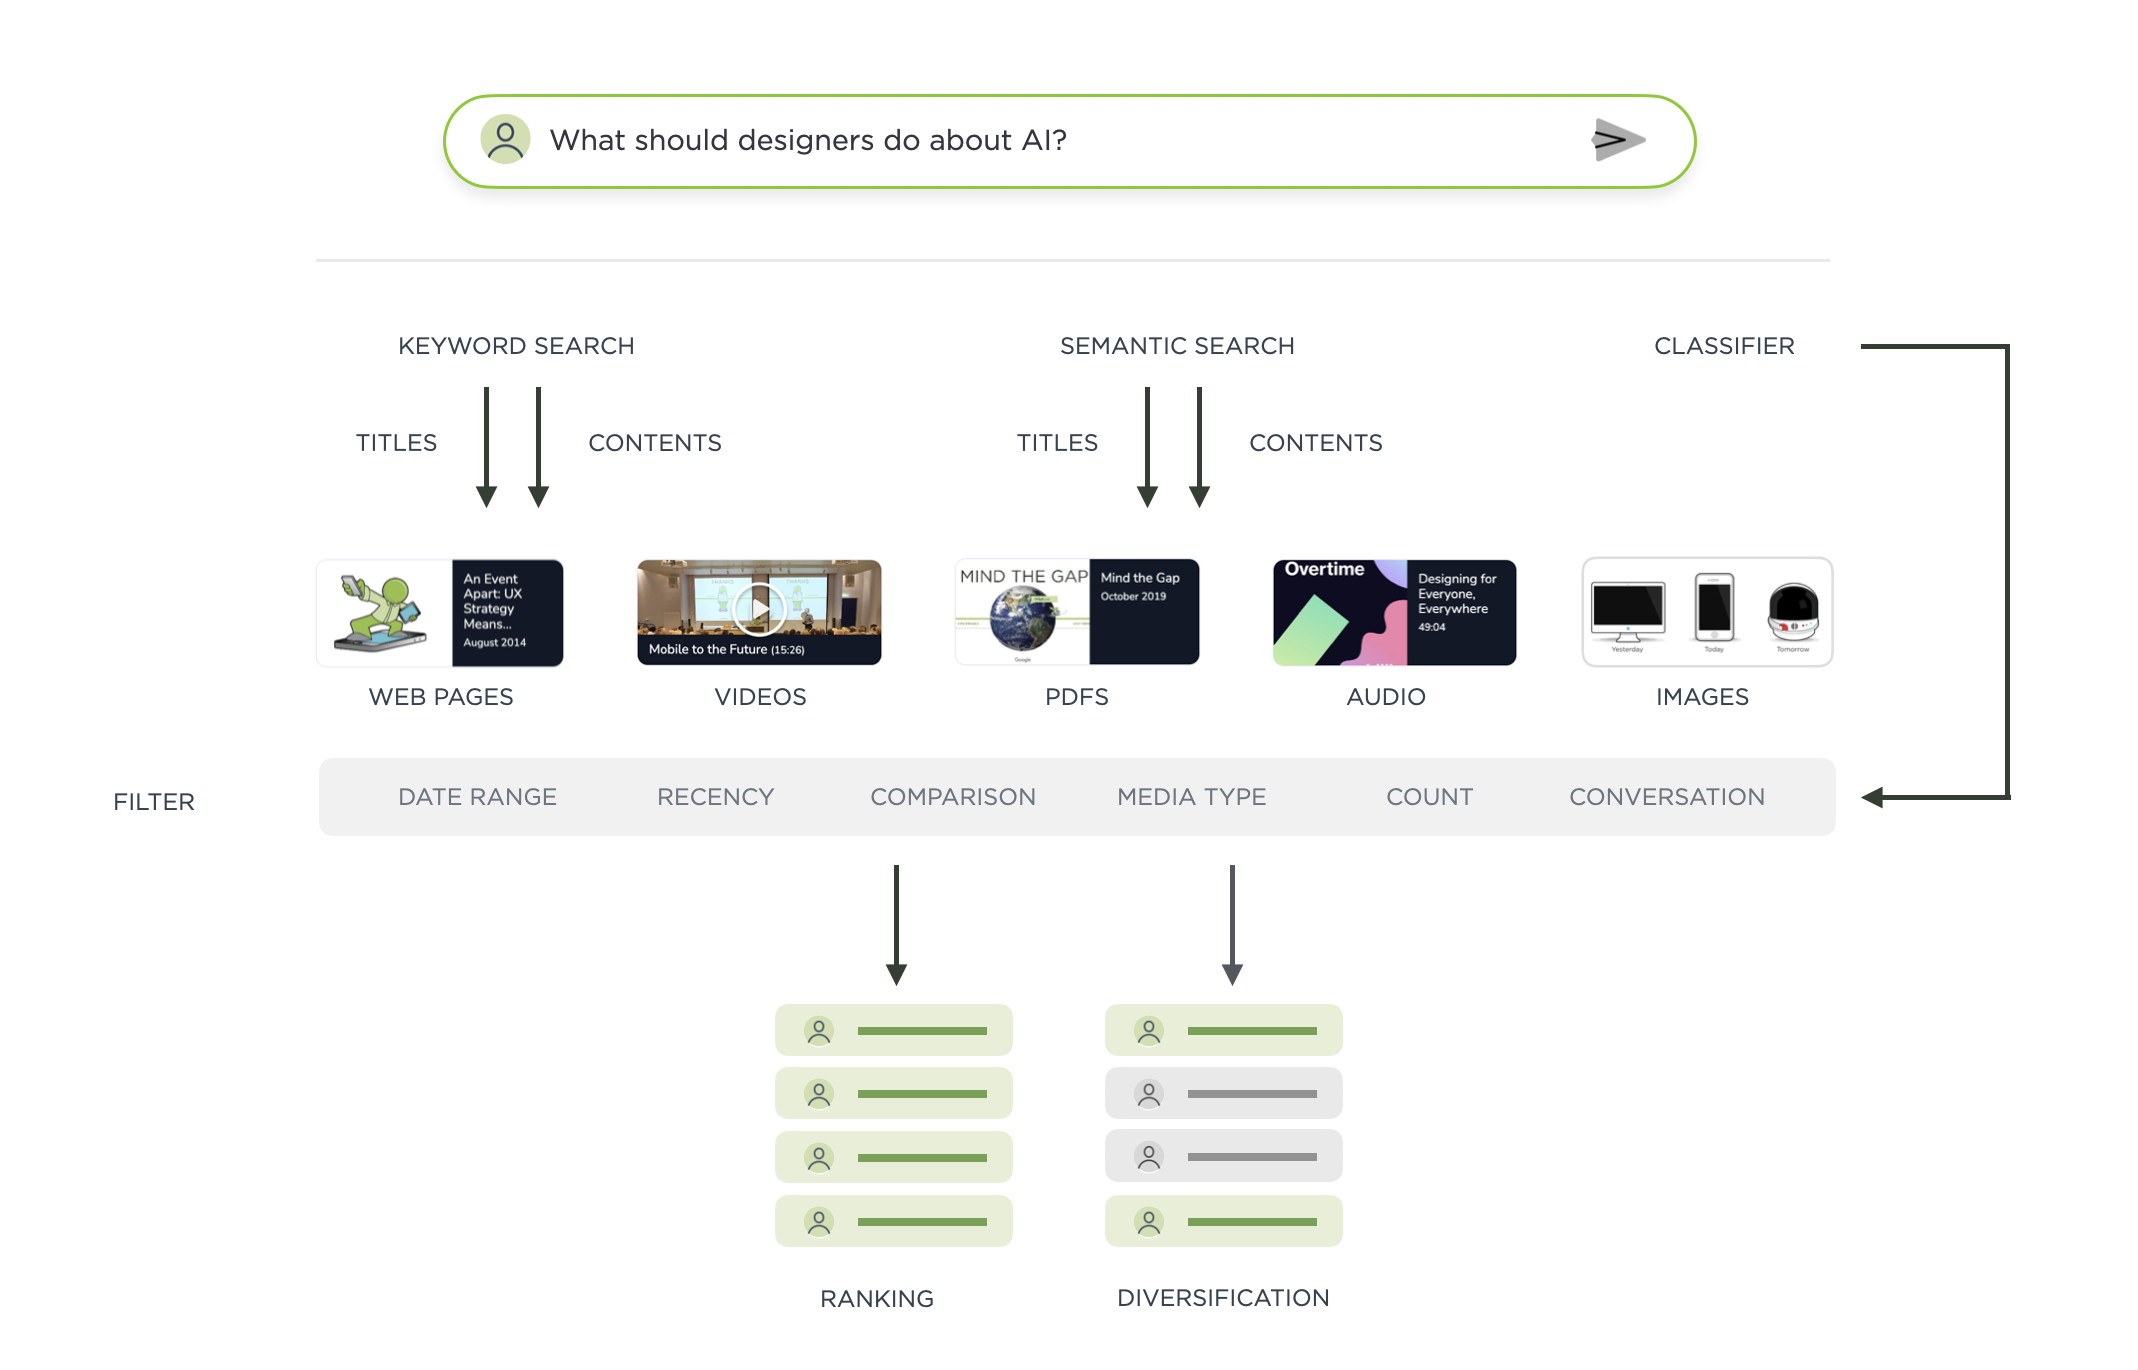
We added a lightweight classifier that analyzes each question being asked and decides how best to search for results: a date range, a recency ordering, a comparison, a specific media type, a count, or a casual conversation. Because a question can be both temporal and media-specific at once (for examples) each classification can stack together. This allows us to better answer...
Temporal Questions
The old system was mostly blind to when I said something. Now it isn't. You can ask things anchored to a moment or a span of time. And it handles the harder version, where the question is about change over time.
- What are you thinking about most recently?
- What did you say about mobile in 2008?
- How have your views changed on AI agents?
- What's the biggest difference between how you thought about AI two years ago and now?
Retrieval Questions
Often people don't want an answer, they want a particular artifact. They half-remember it and describe it. The system now figures out you're after one specific thing and gets it.
- Show me a video of your "AI Ate My Website" talk.
- You wrote an article about Mad Libs forms?
- The podcast where you talked about working at Google?
Quantitative Questions
These are closer to database queries than "find me relevant text" fuzzy text searches. We now recognize that and answer with actual counts and lists instead of a vague summary.
Visual Questions
Some questions are best answered visually, and the response should be an image, not a paragraph describing one. We re-indexed every image posted on my site and can serve up to three per answer. We also cite specific PDF pages and drop in a slide when appropriate.
- What's the difference between AR and VR?
- Why top-aligned labels in forms?
- How to design a pull to refresh feature?
Casual Questions
Sometimes people just want to have fun and ask about random topics. These used to get rejected when no result came back with a message saying I hadn't written about it. Now it recognizes a casual question and answers in kind, often with one of the thousands of LukeW character images people have generated thrown in for personality.
The new retreival system also breaks content into much smaller chunks (yes that's the technical term) to better match specific sentences instead of losing them in a big blob (not a technical term). But small chunks lose their surrounding text and thereby important context, so we pull also in neighboring chunks with each result.
There's still a re-ranking step to make sure we're using only the most relevant results to generate answers. But we tuned things to use 75% re-ranked results and 25% of results from our original embedding search, just to make sure the re-ranker is not over-powering the final result set.
Last but not least we diversify the results so there's not mulitple near-identical chunks that might overpower an answer. But because we now pull in neighbors, a small important set (say the 2008 results) can get washed out by a bigger pile from another result. So we diversify within each result separately.
But Does It Work?
Yes that's a lot of steps but it adds up to better answers. How do we know? Evals of course, this is an AI application after all. But as usual, automatic evals are not enough. Ours was confident the new system was better. But just to be sure, I compared 100 old vs new results by voting on them manually and guess what? The old system won.
Turns out we had a bug, which got fixed. But I mention it because, automatic evals tell you the things moved in the right direction. Human evals find the specific failures you'd otherwise be blind to.
Big thanks to Lukas Seklir, Jerome Paulos, and Sam Breed for this round of changes. I've written about many of the others updates to Ask LukeW over the years, if you want to go deeper into any of it, have at it:
- New Ways into Web Content: rethinking how to design software with AI
- Integrated Audio Experiences & Memory: enabling specific content experiences
- Expanding Conversational User Interfaces: extending chat user interfaces
- Integrated Video Experiences: adding video experiences to conversational UI
- Integrated PDF Experiences: unique considerations when adding PDF experiences
- Dynamic Preview Cards: improving how generated answers are shared
- Text Generation Differences: testing the impact of AI new models
- PDF Parsing with Vision Models: using AI vision models to extract PDF contents
- Streaming Citations: citing relevant articles, videos, PDFs, etc. in real-time
- Streaming Inline Images: indexing & displaying relevant images in answers
- Custom Re-ranker: improving content retrieval to answer more questions
- Usability Study: testing a conversational AI interface with designers
- Generation Model Testing: a personal benchmark for AI model evaluation